I Implemented a Brand-New Research Paper From Scratch — Here’s What I Learned

TinyLLM with Attention Residuals: Why Every Modern LLM Has a Hidden Flaw (And How to Fix It) Every modern LLM you use today — GPT-4, Claude, Gemini, LLaMA — has something in common that almost nobody talks about. They all…

Naresh Matta Avatar

AI Delivery Manager · 15+ yrs in AI & data

7–10 minutes
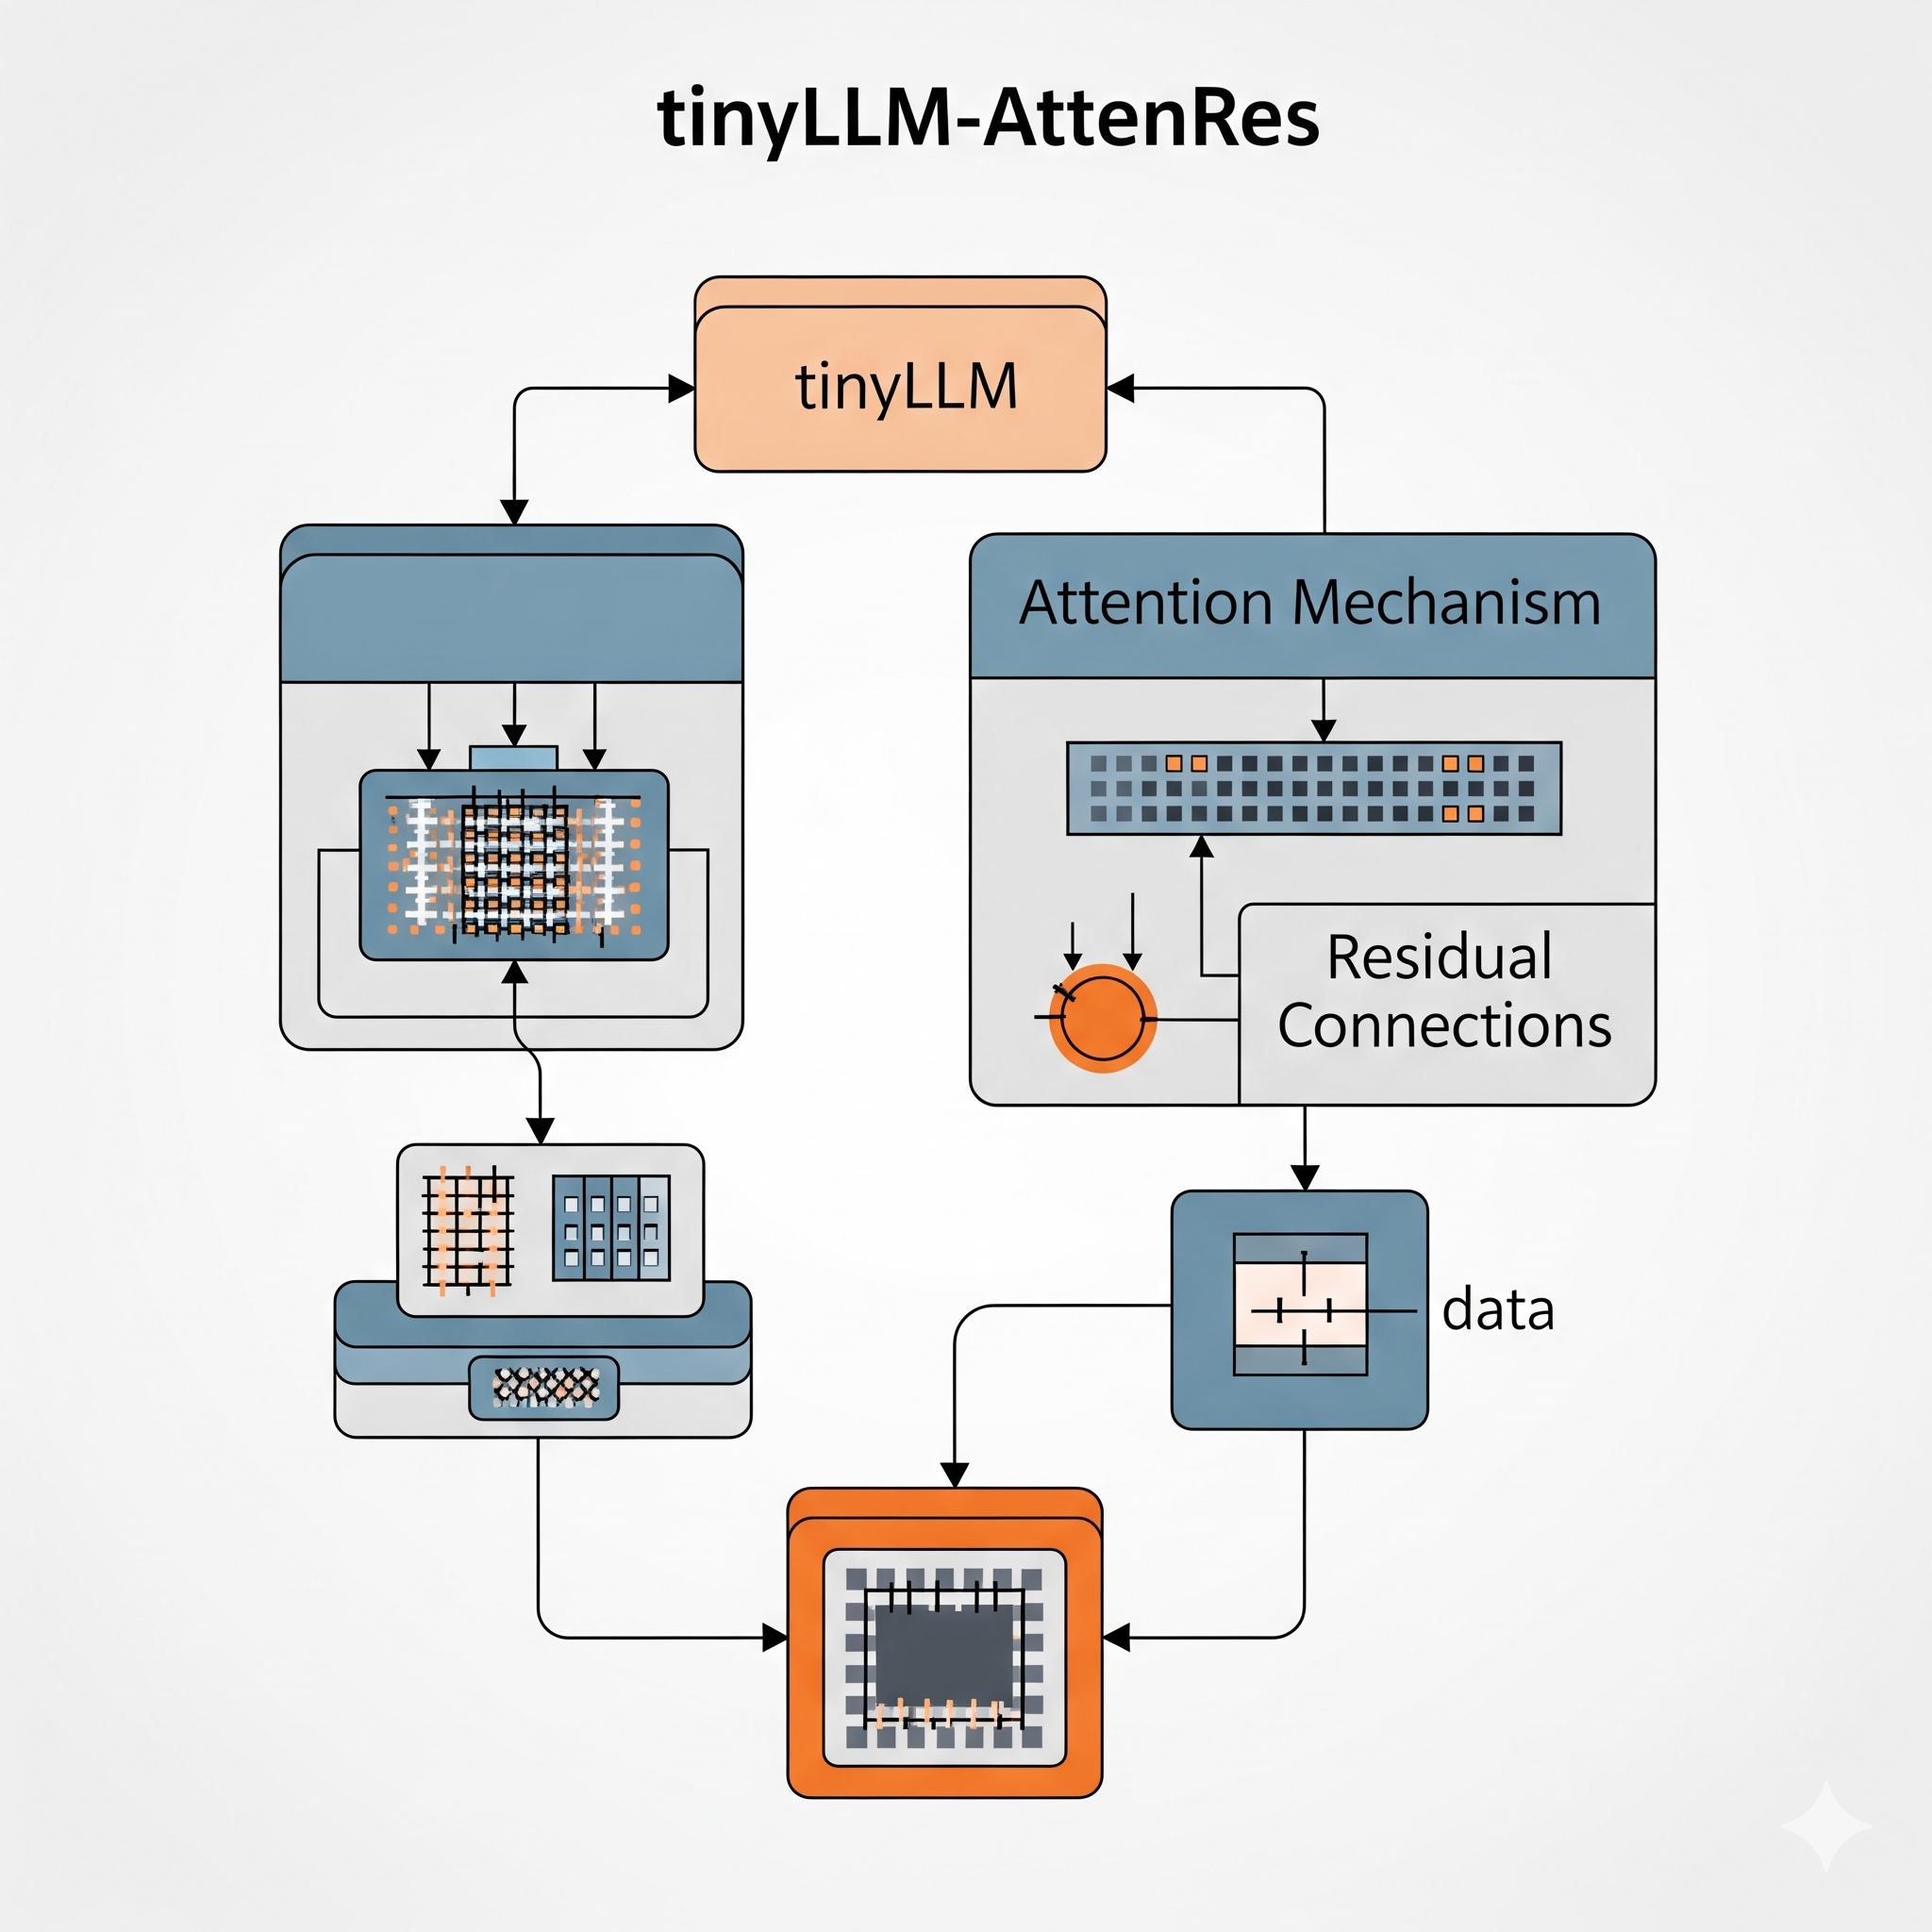
Attention Residuals

TinyLLM with Attention Residuals: Why Every Modern LLM Has a Hidden Flaw (And How to Fix It)


Every modern LLM you use today — GPT-4, Claude, Gemini, LLaMA — has something in common that almost nobody talks about.

They all use the same residual connection design that was introduced back in 2017.

And a brand-new paper published in March 2026 by the Kimi Team at Moonshot AI argues that this design has a fundamental flaw — and proposes a better way.

Subscribe to continue reading

Subscribe to get access to the rest of this post and other subscriber-only content.

Naresh Matta Avatar

About the author

Naresh Matta is an AI Delivery Manager in Bangalore with 15+ years running AI, data and quality programs for large technology clients. He writes SkillWisor to document what he builds and tests.

More about Naresh · LinkedIn · Editorial policy